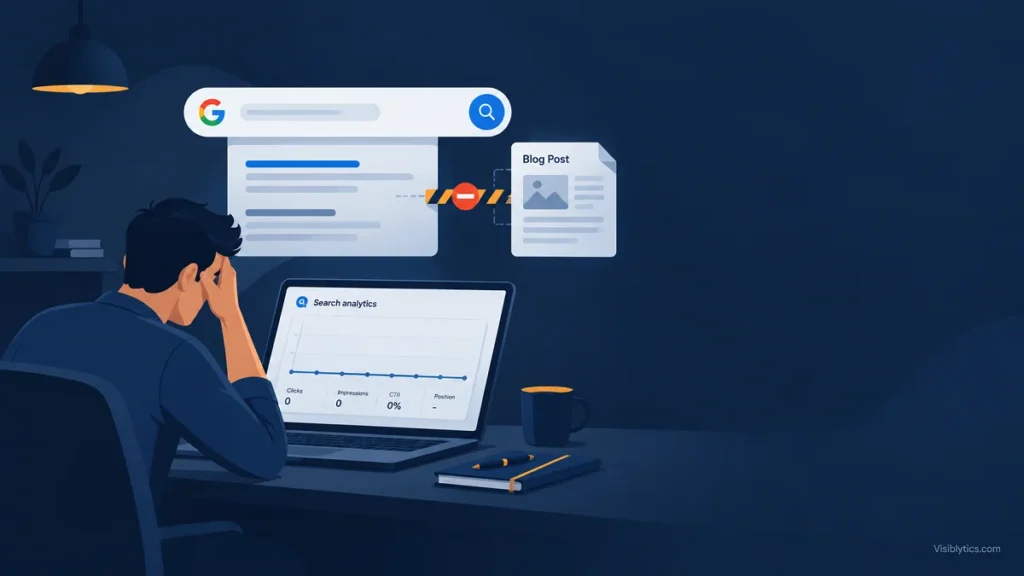
A 2,000-word post, reviewed by two people, published with a clean URL and a decent title tag. Six weeks later, Google Search Console shows a flat line, and someone in the leadership meeting asks what the content budget is actually buying.
This is one of the most expensive quiet failures in content marketing, because the post looks finished. Nothing is visibly broken. But publishing is only the entry ticket. Whether a page ranks depends on four things in a fixed order: whether Google indexed it, whether it matches what searchers wanted when they typed the query, whether your domain has earned the right to compete for that query, and whether your own site gives the page a path to be discovered and trusted.
This article is an autopsy in that order. Treat each check as a gate: if the page fails an earlier gate, fixing a later one changes nothing. You will need Google Search Console, a crawler such as Screaming Frog, and either Ahrefs or Semrush.
The Content Stagnation Dilemma: Great Writing Does Not Mean Google Visibility
The most common mistake in a stalled-content post-mortem is judging the writing. Google does not rank essays; it ranks pages against queries. A beautifully written page can lose to a mediocre one if the mediocre page is indexed, matches the query’s format, sits on a domain with more relevant depth, and is linked from pages Google already trusts.
Before running any checks, open the Performance report in Search Console, filter to the exact URL, and look at the last 28 days. What you see tells you which gate to inspect first. These are rules of thumb from practice, not Google-documented thresholds:
- Zero impressions at all. The page is probably not indexed, or Google has not found it. Start with Check 1 and Check 4.
- Impressions, but average position well beyond page 3. Google knows the page exists and has decided it is a weak answer or comes from a weak source for this query. Start with Check 2 and Check 3.
- Positions around 8–20 with few clicks. The page is close. This is a refresh problem, not a rebuild problem.
The four checks below follow that logic. Work through them in order, and write down what you find for each URL, because the pattern across several stalled posts is often more revealing than any single page.
Check 1: Is the Page Actually Indexed? (The Discovered vs. Crawled Reality)
Do not trust the site: search operator for this. Use the URL Inspection tool in Search Console, paste the exact URL, and read the verdict. If the page is not on Google, open the Page indexing report and find which status it sits under. Two statuses look similar and mean very different things.
Discovered – currently not indexed. Google knows the URL exists (usually from your sitemap or a link) but has not crawled it yet. In practice we read this as a prioritisation signal: Google does not consider the page urgent enough to fetch. Weak internal linking and a site with a lot of low-value URLs both tend to show up here. This is an interpretation, not an official diagnosis, so treat it as a hypothesis to test.
Crawled – currently not indexed. Google fetched the page and decided not to keep it. This points at the page itself: thin or duplicative content, content that adds nothing beyond what is already indexed, or a mismatch with the query. Clicking “Request indexing” again does not change the reason Google declined it, so resubmitting repeatedly is wasted effort.
If the page is indexed, skip ahead. If it is not, rule out the mechanical blockers first:
- A stray noindex. View the page source or the rendered DOM in Chrome DevTools and search for
noindexin both the meta robots tag and theX-Robots-Tagresponse header. Staging settings that survive a launch are a classic cause. - A canonical pointing elsewhere. In URL Inspection, compare “User-declared canonical” with “Google-selected canonical”. If they differ, Google has decided another URL represents this content.
- Robots.txt blocking. URL Inspection will say if the page is blocked from crawling.
- Sitemap omission. Confirm the URL is in your XML sitemap and that the sitemap has been processed in Search Console.
Only after those are clear should you suspect quality as the reason for exclusion, which sends you to Checks 2 and 3.
Check 2: Did You Write for Reader Interest or Exact Search Intent?
This is the check that most “good content, no rankings” cases fail. The question is not whether the post is good. The question is whether it is the kind of page Google is currently rewarding for this exact query.
Run the test in a private browser window. Search your target query and classify the top ten results by format: product or service pages, tools and calculators, comparison listicles, step-by-step tutorials, forum threads, definitions. If nine of the ten are product pages and you published a thought-leadership essay, you did not write a weaker version of the winning page. You wrote a different kind of page, and no amount of polish will move it.
A concrete example: a founder targets “project management software for agencies” and publishes “Why Agencies Struggle With Project Delivery”. The writing is sharp, but the query is a vendor-evaluation query. The SERP is a wall of comparison pages and software category pages. The essay answers a question nobody typed.
When you find a mismatch, you have two options. Rewrite the page into the format the SERP rewards, or retarget the essay at a query where an essay is the right answer. Both are legitimate; leaving it as is, is not.
Three quick tells that intent is off:
- Your title tag promises something different from what the top results promise.
- Your H1 is a clever phrase rather than the language searchers use.
- The query surfaces a SERP feature you are not built to win, such as a map pack or a tool carousel.
For the full framework on classifying intent types, see our complete guide to search intent. For title formulas that align a page with the query, our title tag best practices guide covers the mechanics so we do not need to repeat them here.
Check 3: The Topical Authority Gap (Why High-DR Competitors Beat Better Articles)
Your article can be better than the one in position three and still lose, because Google does not evaluate your article in isolation. It evaluates the page in the context of the site that publishes it.
A useful reality check: open Ahrefs or Semrush and look at the domain that outranks you. Ignore the headline authority score, which is a third-party metric and not something Google uses. Instead, look at how many pages that domain has covering the surrounding subtopics, and how many of them rank for related queries. A competitor with 25 interlinked pages on a topic has built a cluster. Your single post is one page standing next to it.
Two diagnostic questions make this concrete:
- What is the hardest keyword your domain currently ranks in the top ten for? If your new target sits far above that level of difficulty, expect a long climb or none at all, regardless of content quality.
- Does your site have supporting pages for this topic? If the post is a one-off, with nothing else on the site covering adjacent questions, you are asking Google to trust a page with no context.
The fixes are strategic rather than editorial. You can retarget to a narrower long-tail query where your domain can realistically compete, then expand outward. Or you can commit to building the cluster around the page, with supporting articles that link back to it. Which route is right depends on how competitive the query is and how much runway you have. A freelance keyword research specialist typically starts exactly here, mapping which queries your domain can win now and which need cluster-building first.
Check 4: The Orphan Page Trap (Lack of Internal Link Architecture)
A new post is invisible to everyone, including Google, unless something points to it. Many sites publish a post, let it appear on the blog index for a few days, and never link to it again. Within weeks it is buried under newer posts on a paginated index nobody crawls deeply.
To check this properly:
- Run a crawl in Screaming Frog with your sitemap and the Search Console API connected. Pages that appear in the sitemap or in Search Console but were not reached by the crawl are orphans.
- Open the Links report in Search Console and look at internal links to the URL. A count in the low single digits, or links only from footers and index pages, is a weak signal.
- Check where the links come from. A link from a page that already earns impressions and clicks carries far more weight than a link from a page nobody visits.
The fix is simple and routinely skipped. As a rule of thumb, add three to five contextual links from relevant pages that already rank or receive traffic, using descriptive anchor text that tells readers and Google what the target page covers. Also place the post in the relevant hub or category page if you have one. Avoid generic anchors such as “click here” or “read more”.
This is also the cheapest check on the list. If Check 1 flagged “Discovered – currently not indexed”, fixing internal links is often the first thing to try.
How to Perform a Content Refresh That Revives Stalled Rankings
Diagnose first, then refresh. Rewriting a post without knowing which gate it failed is how teams spend a week on edits that change nothing.
Use this table to connect what you see in Search Console to the likely cause and the right next move.
Content refresh diagnostic checklist
| Symptom | Likely gate | How to confirm | Fix |
|---|---|---|---|
| Zero impressions after several weeks | Indexation or discovery | URL Inspection; Page indexing report | Remove blockers (noindex, canonical, robots); add internal links; include in sitemap |
| “Discovered – currently not indexed” | Crawl prioritisation | Page indexing report; internal link count | Add contextual internal links from pages that already get traffic; prune low-value URLs |
| “Crawled – currently not indexed” | Page quality or duplication | Compare against top-ranking pages for added value | Add original information; consolidate overlapping pages; rewrite to match intent |
| Impressions but average position beyond page 3 | Intent or authority | Incognito SERP review; compare domain depth in Ahrefs/Semrush | Rewrite to the dominant format or retarget to a winnable long-tail query |
| Ranking for unrelated queries only | Intent mismatch | Queries tab in Performance report | Align title, H1, and intro to the target query |
| Positions 8–20, low clicks | Refresh opportunity | Performance report filtered to URL | Strengthen title tag; fill content gaps vs. top results; add internal links |
| Page ranks, then drops | Competition or cannibalisation | Check for another of your URLs ranking for the same query | Consolidate or differentiate overlapping pages |
| Indexed, ranking, no conversions | Wrong audience or weak call to action | Landing page behaviour in analytics | Reconsider the query target; revisit the CTA |
Once you know the gate, a refresh follows a consistent sequence:
- Pull the real queries. In Search Console, filter to the URL and export queries with impressions. These tell you what Google thinks the page is about, which may differ from what you intended.
- Rewrite the title, H1, and opening to match the dominant query and intent. Do not change the URL unless you have a strong reason; changing it resets signals and needs a redirect.
- Add information gain. Compare your page to the top three results and ask what they have that you left out, then ask what you can add that none of them have: original data, a proprietary framework, screenshots, a worked example. Rewording what is already ranking gives Google no reason to prefer yours.
- Restructure for scannability. Clear H2 and H3 hierarchy, direct answers near the top of each section, and tables where comparison is the point.
- Add internal links in both directions. Link to the refreshed page from relevant, stronger pages, and link out from it to related pages that support the cluster.
- Update the publication date only for substantive changes. Cosmetic date changes do not fool anyone and erode reader trust.
- Re-inspect and request indexing, then wait. As a rule of thumb, give a refreshed page several weeks before judging it, and measure against impressions and average position, not just clicks.
One caution: refreshing is not the answer to every failed post. If the diagnosis says the query is out of reach for your domain right now, polishing the page is the wrong lever. Retarget it, or build the supporting content it needs first.
Why Experienced Teams Bring In a Freelance On-Page SEO Expert
Everything above is doable in-house. A marketing manager with Search Console access and a free afternoon can run the indexation check, the SERP format test, and the internal link audit for a single URL. For a single stalled post, that may be all you need.
It stops scaling when you have dozens of underperforming pages, because the real cost is not any one diagnosis. It is the judgement calls in between: which pages to refresh, which to consolidate, which to retarget, and which to leave alone. Those calls depend on seeing patterns across many URLs, and a single mistaken consolidation can erase rankings you already had. Rates for senior freelance SEO work are commonly quoted in the range of $150–$250 per hour, though you should verify current rates against quotes from the people you are considering. That is typically far cheaper than months of misdirected content spend.
This is where an on-page SEO expert who optimizes content for real ranking performance earns the fee: auditing the whole library against intent, authority, and architecture, then sequencing the fixes by likely return. One honest note: nobody can guarantee a ranking, and anyone who does is not being straight with you. What a specialist can credibly offer is a clearer diagnosis, a prioritised plan, and execution that does not repeat the mistakes above.
If you want a second pair of eyes on a post that is stuck, start with the four checks in this article. If they do not explain the stall, or if the problem looks site-wide rather than page-specific, that is the point to bring in outside help.